
非官方中文翻译
本页译自 MNE-Python 官方文档:
查看英文原文 ↗。
文档版权归 MNE Developers 所有(BSD-3-Clause)。
说明
转到末尾下载完整示例代码。
表征相似性分析#
表征相似性分析(RSA)用于在类别数较多的监督分类上做汇总统计。它通过刻画混淆矩阵的结构来推断脑响应之间的相似性,可作为刻画心理表征空间的代理指标 [1] [2] [3]。
本示例对 24 张物体图像(取自 92 张图像列表)的响应做 RSA。实验中向被试呈现人、动物与无生命物体的图像 [4];这里使用其中 24 张面孔与身体部位的唯一图像。
说明
本示例需要约 6 GB 的 data_path() 数据集,因此首次运行可能需要较长时间。
# Authors: Jean-Rémi King <jeanremi.king@gmail.com>
#          Jaakko Leppakangas <jaeilepp@student.jyu.fi>
#          Alexandre Gramfort <alexandre.gramfort@inria.fr>
#
# License: BSD-3-Clause
# Copyright the MNE-Python contributors.
import matplotlib.pyplot as plt
import numpy as np
from pandas import read_csv
from sklearn.linear_model import LogisticRegression
from sklearn.manifold import smacof
from sklearn.metrics import roc_auc_score
from sklearn.model_selection import StratifiedKFold
from sklearn.multiclass import OneVsRestClassifier
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

import mne
from mne.datasets import visual_92_categories
from mne.io import concatenate_raws, read_raw_fif

print(__doc__)

data_path = visual_92_categories.data_path()

# Define stimulus - trigger mapping
fname = data_path / "visual_stimuli.csv"
conds = read_csv(fname)
print(conds.head(5))
   trigger       condition  human  face  animal  natural
0        0  human bodypart      1     0       1        1
1        1  human bodypart      1     0       1        1
2        2  human bodypart      1     0       1        1
3        3  human bodypart      1     0       1        1
4        4  human bodypart      1     0       1        1
为加快计算,我们限制条件数量
max_trigger = 24
conds = conds[:max_trigger]  # take only the first 24 rows
定义刺激—触发器映射
conditions = []
for c in conds.values:
    cond_tags = list(c[:2])
    cond_tags += [
        ("not-" if i == 0 else "") + conds.columns[k] for k, i in enumerate(c[2:], 2)
    ]
    conditions.append("/".join(map(str, cond_tags)))
print(conditions[:10])
['0/human bodypart/human/not-face/animal/natural', '1/human bodypart/human/not-face/animal/natural', '2/human bodypart/human/not-face/animal/natural', '3/human bodypart/human/not-face/animal/natural', '4/human bodypart/human/not-face/animal/natural', '5/human bodypart/human/not-face/animal/natural', '6/human bodypart/human/not-face/animal/natural', '7/human bodypart/human/not-face/animal/natural', '8/human bodypart/human/not-face/animal/natural', '9/human bodypart/human/not-face/animal/natural']
构建 event_id 字典
event_id = dict(zip(conditions, conds.trigger + 1))
event_id["0/human bodypart/human/not-face/animal/natural"]
读取 MEG 数据
n_runs = 4  # 4 for full data (use less to speed up computations)
fnames = [data_path / f"sample_subject_{b}_tsss_mc.fif" for b in range(n_runs)]
raws = [
    read_raw_fif(fname, verbose="error", on_split_missing="ignore") for fname in fnames
]  # ignore filename warnings
raw = concatenate_raws(raws)

events = mne.find_events(raw, min_duration=0.002)

events = events[events[:, 2] <= max_trigger]
Finding events on: STI101
4142 events found on stim channel STI101
Event IDs: [  1   2   3   4   5   6   7   8   9  10  11  12  13  14  15  16  17  18
  19  20  21  22  23  24  25  26  27  28  29  30  31  32  33  34  35  36
  37  38  39  40  41  42  43  44  45  46  47  48  49  50  51  52  53  54
  55  56  57  58  59  60  61  62  63  64  65  66  67  68  69  70  71  72
  73  74  75  76  77  78  79  80  81  82  83  84  85  86  87  88  89  90
  91  92  93 200 222 244]
对数据分段
Not setting metadata
720 matching events found
No baseline correction applied
0 projection items activated
Loading data for 720 events and 601 original time points ...
0 bad epochs dropped
绘制部分条件的响应
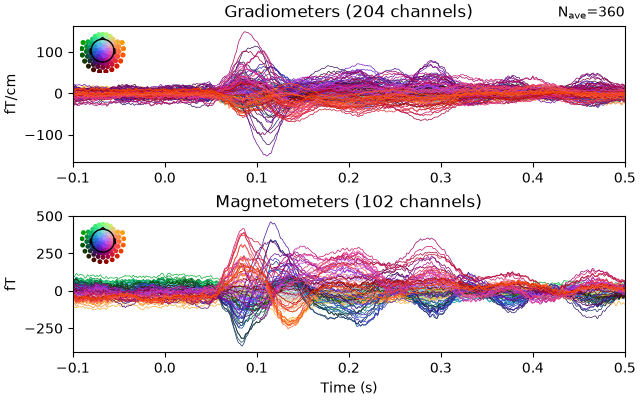
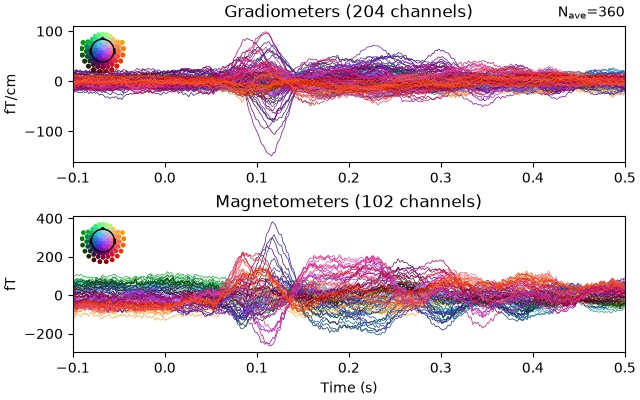
表征相似性分析(RSA)是神经影像领域的专门叫法,指对混淆矩阵(也称表征相异性矩阵,RDM)所做的统计。
与 Cichy 等人的做法相比,我们使用多类分类器(多项式逻辑回归),而原论文用所有成对二分类任务构建 RDM;这里用 ROC-AUC 作为性能指标,原论文用准确率。最后,为节省时间,我们只在一个数据窗口上做 RSA,而 Cichy 等人对每个时间点分别计算。
# Classify using the average signal in the window 50ms to 300ms
# to focus the classifier on the time interval with best SNR.
clf = make_pipeline(
    StandardScaler(),
    OneVsRestClassifier(LogisticRegression(C=1, random_state=79)),
)
X = epochs.get_data(tmin=0.05, tmax=0.3).mean(axis=2)
y = epochs.events[:, 2]

classes = set(y)
cv = StratifiedKFold(n_splits=5, random_state=83, shuffle=True)

# Compute confusion matrix for each cross-validation fold
y_pred = np.zeros((len(y), len(classes)))
for train, test in cv.split(X, y):
    # Fit
    clf.fit(X[train], y[train])
    # Probabilistic prediction (necessary for ROC-AUC scoring metric)
    y_pred[test] = clf.predict_proba(X[test])
使用 ROC-AUC 计算混淆矩阵
绘图
labels = [""] * 5 + ["face"] + [""] * 11 + ["bodypart"] + [""] * 6
fig, ax = plt.subplots(1, layout="constrained")
im = ax.matshow(confusion, cmap="RdBu_r", clim=[0.3, 0.7])
ax.set_yticks(range(len(classes)))
ax.set_yticklabels(labels)
ax.set_xticks(range(len(classes)))
ax.set_xticklabels(labels, rotation=40, ha="left")
ax.axhline(11.5, color="k")
ax.axvline(11.5, color="k")
plt.colorbar(im)
plt.show()
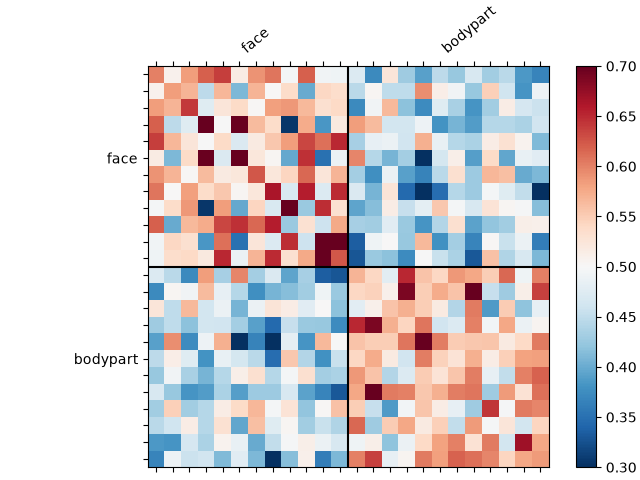
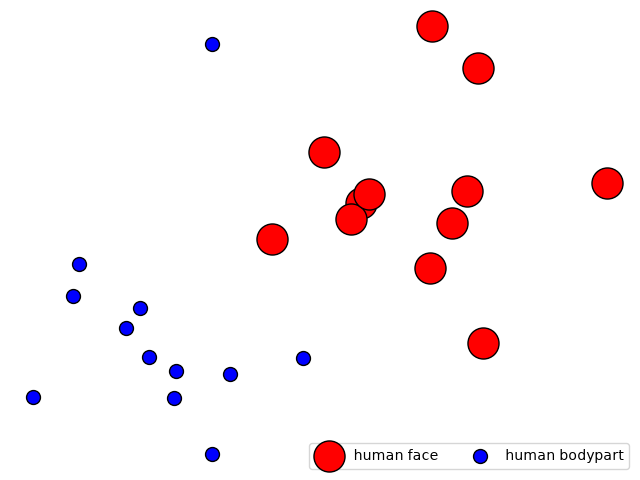
与心理表征相关的混淆矩阵历来通过多维尺度分析等降维方法进行汇总 [1]。可以看到面孔样本聚在一起。
fig, ax = plt.subplots(1, layout="constrained")
chance = 0.5
# TODO VERSION: this is MDS(2, n_init=4, init='random', metric='precomputed'),
# but that spelling requires scikit-learn >= 1.8
summary, _ = smacof(chance - confusion, n_components=2, n_init=4, random_state=89)
cmap = plt.colormaps["rainbow"]
colors = ["r", "b"]
names = list(conds["condition"].values)
for color, name in zip(colors, set(names)):
    sel = np.where([this_name == name for this_name in names])[0]
    size = 500 if name == "human face" else 100
    ax.scatter(
        summary[sel, 0],
        summary[sel, 1],
        s=size,
        facecolors=color,
        label=name,
        edgecolors="k",
    )
ax.axis("off")
ax.legend(loc="lower right", scatterpoints=1, ncol=2)
plt.show()
参考文献#
脚本总运行时间:(0 分 23.470 秒)